Data Scientist Resume Examples & Format Guide (2026)
See 3 real data science resume examples (entry-level, mid-level, senior) plus the best resume format, summaries, bullet points, skills and ATS keywords.
A strong data scientist resume proves three things fast: what kind of problems you solve (forecasting, experiments, churn, pricing, NLP), which tools you use to solve them (Python, SQL, scikit-learn, XGBoost, Spark), and what changed for the business because of your work. Below are three complete data science resume examples, one each for an entry-level graduate, a mid-level data scientist and a senior team lead, followed by the best resume format for data scientists and the summaries, bullet points, skills and ATS keywords you can adapt.
Every data science bullet needs two numbers: a model or analysis number (AUC, MAPE, sample size, p-value) and a business number (revenue, cost, time saved, conversion). A model metric alone tells a recruiter you can train a model; the business number tells them it mattered.
Data Science Resume Examples
Each example below is a full one-page resume built with the free Jake's Resume template, the single-column LaTeX-style layout many data scientists already use, which parses cleanly in applicant tracking systems (ATS). The people and companies are made up; the tools, data sizes and metrics are realistic for each level. Click any resume to open it full size.
Entry-Level Data Scientist Resume Example
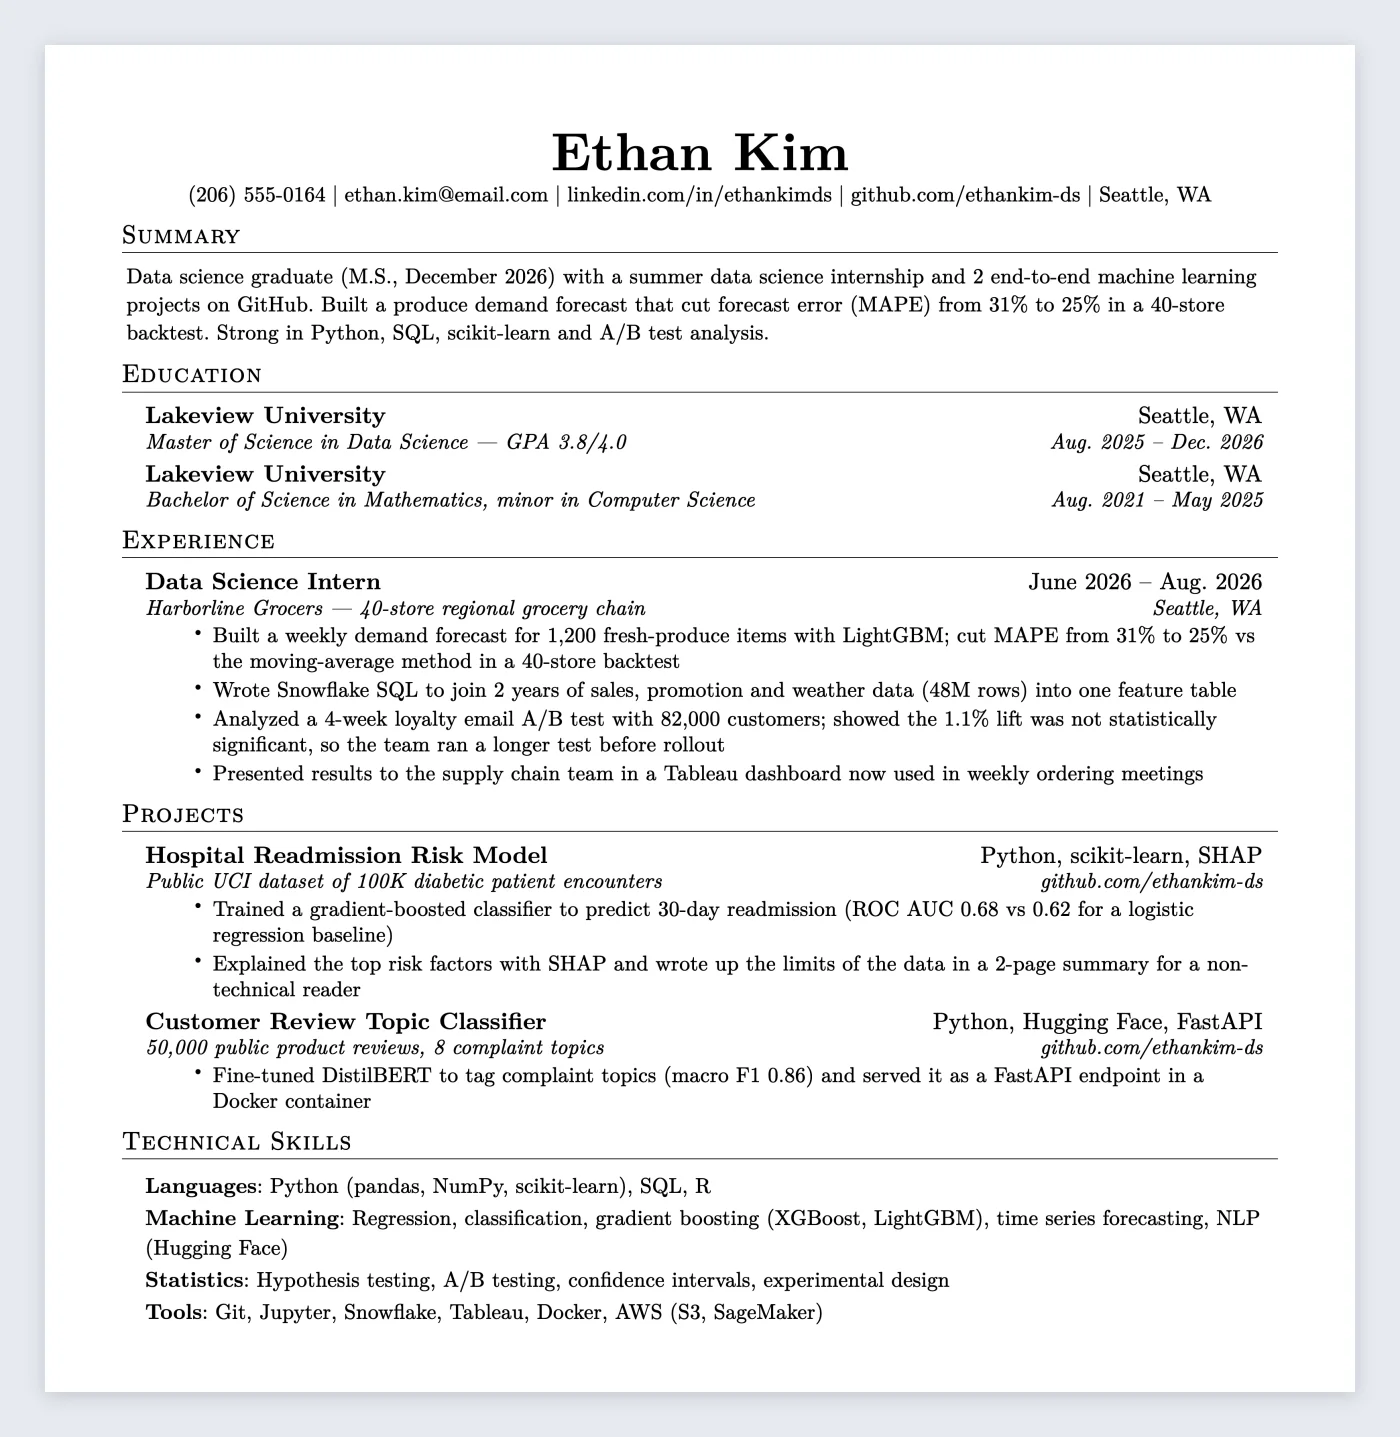
Why this resume works:
- Education comes first because the master's degree is the newest and strongest credential, and the internship is the only industry role.
- The internship reads like a real job. Each bullet names the tool (LightGBM, Snowflake, Tableau) and the size of the data (1,200 items, 48M rows, 82,000 customers).
- It shows statistical honesty. Reporting that an A/B test lift was not significant is a strong signal: hiring managers want people who will not oversell results.
- Projects use real public data and report a baseline (AUC 0.68 vs 0.62), not just a single score. A recruiter can click the GitHub link and check the work.
Mid-Level Data Scientist Resume Example
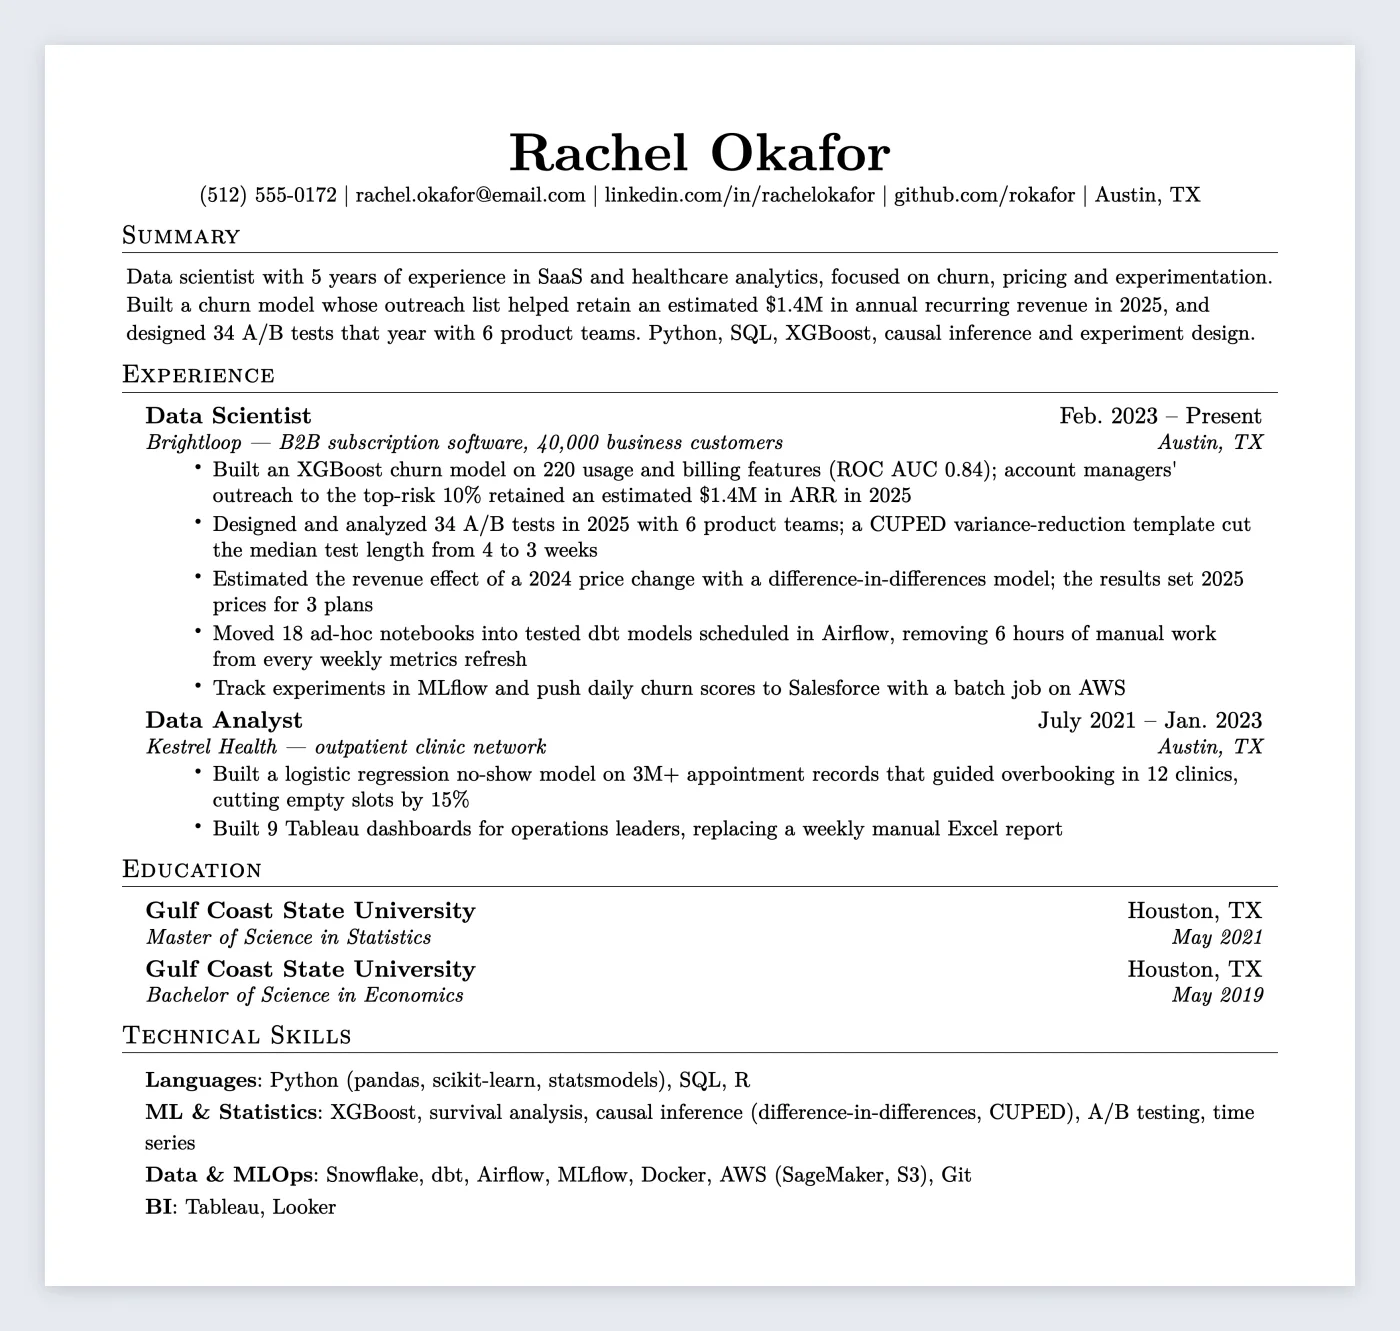
Why this resume works:
- The summary leads with business results: an estimated $1.4M in recurring revenue retained and 34 A/B tests in a year.
- It covers the three things most data scientist job posts ask for: predictive modeling (churn), experimentation (A/B tests, CUPED) and causal inference (difference-in-differences).
- Production work is visible. dbt, Airflow, MLflow and a daily scoring job show the models are used, not left in a notebook.
- The analyst role stays short but shows the path from analyst to data scientist, which is the most common route into the field.
Senior Data Scientist Resume Example
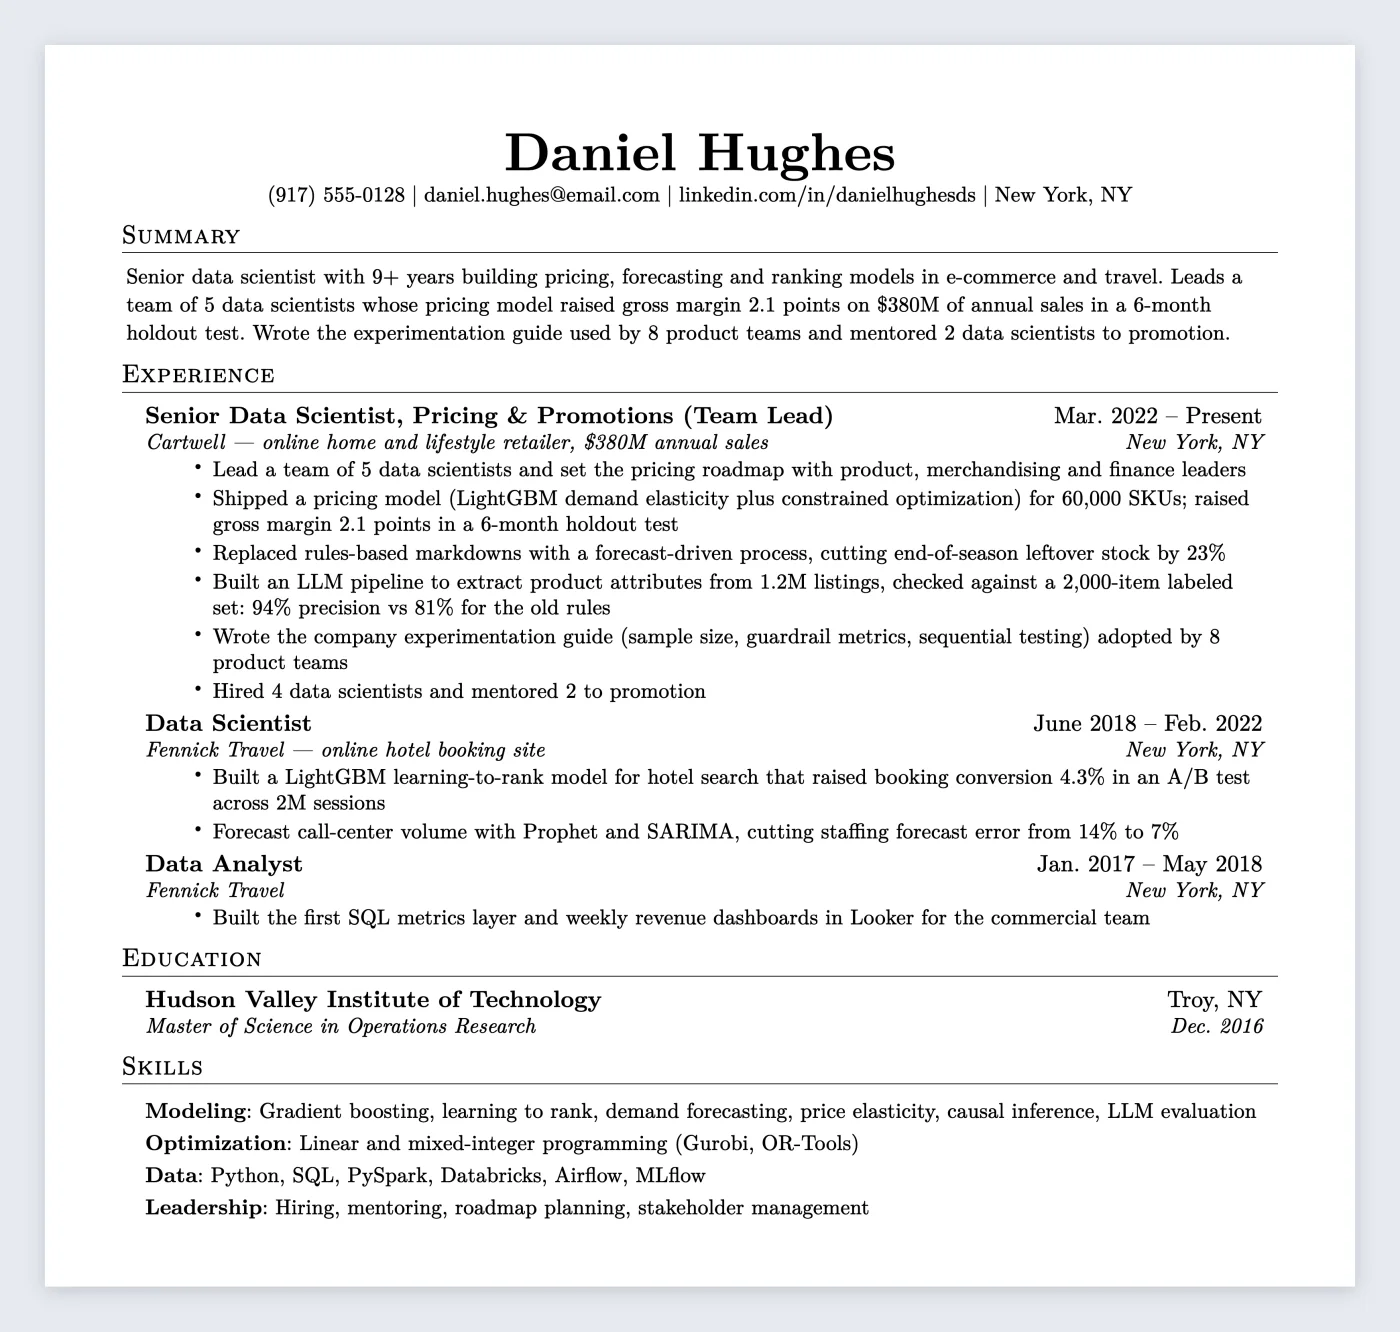
Why this resume works:
- Impact is stated at company scale: 2.1 points of gross margin on $380M of sales, measured in a holdout test, not a guess.
- Leadership is concrete: team size, roadmap ownership, hiring and promotions.
- It includes modern work done carefully. The LLM pipeline is judged against a labeled set (94% vs 81% precision), which is exactly how interviewers expect LLM work to be measured.
- Early roles get one or two lines, keeping the resume to one page while the last 4 years get the space.
Resume Format for Data Scientists
The best resume format for a data scientist is a one-page, single-column, reverse-chronological resume saved as a PDF, with links to GitHub, a portfolio or published work in the header. Skip skill bars, star ratings, photos and two-column designs: they waste space and can scramble in ATS parsers.
The right section order depends on your experience:
| Experience level | Section order | Length |
|---|---|---|
| Student / new graduate | Summary, Education, Experience or Internships, Projects, Technical Skills | 1 page |
| Career changer (analyst, engineer, scientist) | Summary, Technical Skills, Experience (data work first), Projects, Education | 1 page |
| Mid-level / 2–6 years | Summary, Experience, Technical Skills, Education | 1 page |
| Senior, lead or manager | Summary, Experience, Skills, Education, Publications or Patents (if any) | 1–2 pages |
| PhD moving to industry | Summary, Education (thesis in one line), Research and Industry Experience, Projects, Skills, Selected Publications | 1–2 pages |
Keep fonts at 10–11 pt, margins near 0.5 inch, and dates right-aligned. Write metrics in plain words a recruiter understands ("forecast error fell from 31% to 25%"), and name the technical metric once in brackets if it helps ("MAPE").
Data scientist vs data analyst vs ML engineer resume
These three roles overlap, so the same experience should be framed differently for each:
| Role | What the resume should lead with | Typical tools to put first |
|---|---|---|
| Data analyst | Dashboards, reporting, SQL analysis and decisions it informed | SQL, Excel, Tableau or Power BI, Python |
| Data scientist | Models, experiments and statistical analysis tied to business results | Python, SQL, scikit-learn, XGBoost, statistics, A/B testing |
| Machine learning engineer | Models in production: pipelines, serving, latency, scale, monitoring | Python, PyTorch or TensorFlow, Docker, Kubernetes, cloud ML services |
If you are applying for a more engineering-heavy role, see our machine learning engineer resume example and data engineer resume example.
Data Scientist Resume Summary Examples
A summary is two or three sentences that say what kind of data scientist you are, your strongest result, and the skills the job post asks for most. Use this formula:
[Role] with [X years] in [domain]. [Best result with a business number]. [Top 3–5 skills from the job post].
Entry-level (new graduate):
Data science graduate (M.S., December 2026) with a summer internship and 2 end-to-end machine learning projects on GitHub. Built a produce demand forecast that cut forecast error from 31% to 25% in a 40-store backtest. Strong in Python, SQL, scikit-learn and A/B test analysis.
Data analyst moving into data science:
Data analyst with 3 years in e-commerce analytics, moving into data science. Built a logistic regression model that flagged high-risk orders and cut chargebacks 18%, and analyze 10+ A/B tests a quarter. Python, SQL, statsmodels, Tableau.
PhD moving to industry:
Physics PhD with 5 years of experience building statistical models on large, noisy sensor datasets (2B+ records). Wrote production-quality Python packages used by 30 researchers. Looking to apply Bayesian modeling, time series and experiment design to product problems.
Mid-level data scientist:
Data scientist with 5 years in SaaS and healthcare analytics, focused on churn, pricing and experimentation. Built a churn model that helped retain an estimated $1.4M in recurring revenue and ran 34 A/B tests in a year with 6 product teams. Python, SQL, XGBoost, causal inference.
Senior data scientist:
Senior data scientist with 9+ years in e-commerce and travel. Lead a team of 5 whose pricing model raised gross margin 2.1 points on $380M of annual sales in a holdout test. Set experimentation standards for 8 product teams.
Data Scientist Resume Bullet Points
Strong data science bullets follow one pattern: action verb + what you built or analyzed + method and data size + model metric + business result. Pick the ones that match your real work and change the numbers to yours.
Machine learning and predictive modeling
- Built an XGBoost churn model on 220 usage and billing features (ROC AUC 0.84); outreach to the top-risk 10% retained an estimated $1.4M in ARR.
- Built a weekly demand forecast for 1,200 products with LightGBM, cutting MAPE from 31% to 25% against the moving-average baseline.
- Trained a fraud model on 12M transactions that caught 22% more fraud at the same false-positive rate, saving about $600K a year.
Experimentation and statistics
- Designed and analyzed 34 A/B tests in a year with 6 product teams; added CUPED variance reduction that cut median test length from 4 to 3 weeks.
- Estimated the effect of a price change with a difference-in-differences model; the results set prices for 3 plans.
- Found that a promising 1.1% lift was not statistically significant, so the team ran a longer test before rollout.
Analytics and business impact
- Segmented 400K customers with k-means on purchase behavior; the marketing team's new campaigns for 2 segments raised repeat purchase rate 9%.
- Built a no-show model on 3M+ appointment records that guided overbooking in 12 clinics and cut empty slots 15%.
Data pipelines and MLOps
- Moved 18 ad-hoc notebooks into tested dbt models scheduled in Airflow, removing 6 hours of manual work from every weekly refresh.
- Deployed a scoring model as a daily batch job on AWS and tracked versions and metrics in MLflow.
NLP and LLMs
- Fine-tuned DistilBERT to tag support tickets into 8 topics (macro F1 0.86), routing 40% of tickets without manual triage.
- Built an LLM pipeline to extract product attributes from 1.2M listings and checked it on a 2,000-item labeled set: 94% precision vs 81% for the old rules.
Leadership
- Led a team of 5 data scientists and set the pricing roadmap with product, merchandising and finance leaders.
- Hired 4 data scientists and mentored 2 to promotion; wrote the experimentation guide adopted by 8 product teams.
How to quantify data science work
| Type of work | Model or analysis number | Business number |
|---|---|---|
| Classification (churn, fraud, risk) | ROC AUC, precision and recall, lift at top 10% | Revenue retained, fraud losses avoided, manual reviews saved |
| Forecasting | MAPE, WAPE or RMSE vs the old method | Stockouts, waste, staffing cost, inventory value |
| Experiments | Sample size, effect size, confidence interval | Conversion, revenue, retention, decision made |
| Ranking and recommendations | NDCG, click-through rate in an A/B test | Bookings, orders, revenue per session |
| Automation and pipelines | Rows processed, refresh time, data quality checks | Hours saved per week, faster decisions |
| LLM and NLP | F1 or precision on a labeled evaluation set | Tickets routed, listings enriched, hours saved |
If you do not have an exact business number, use an honest estimate and say so ("an estimated $1.4M"), or describe the decision your work changed.
Projects That Strengthen a Data Science Resume
For entry-level candidates and career changers, projects often decide the interview. The strongest projects:
- Answer a real question with a real or public dataset, not the Titanic or Iris datasets every course uses.
- Compare against a baseline (a simple model or the current method) so the result has meaning.
- Go end to end: data cleaning, modeling, evaluation, and a short write-up or a small deployed demo.
- Live in a clean GitHub repo with a README that states the problem, data, method and result in the first paragraph.
Put 2–3 projects on the resume, each with 1–2 bullets and the main tools on the right of the title line, as in the entry-level example above. Our Python developer resume example shows how to present code-heavy projects.
How to Write a Data Scientist Resume With No Experience
If you are a student or switching careers, you need proof of data science work, not a longer objective:
- Turn coursework and capstones into projects with a dataset, a method, a metric and a baseline.
- Look for data in your current job. Analysts, engineers, scientists and even operations staff often have a forecasting, reporting or automation problem they can solve with Python and SQL. That becomes your best bullet.
- Do one internship, research assistant role or volunteer analysis (nonprofits and university labs often need help) and list it like a job.
- Lead with Education or Technical Skills, then Projects, until you have a data science job title.
- Show statistics, not just libraries. Mention hypothesis testing, experiment design or regression in at least one bullet; many data scientist interviews include a statistics round.
Skills for a Data Scientist Resume
List the tools you have actually used, grouped by type. Interviewers often pick one skill from your list and ask you to explain a project where you used it.
- Languages: Python (pandas, NumPy, scikit-learn), SQL, R
- Machine learning: regression, classification, gradient boosting (XGBoost, LightGBM), clustering
- Statistics: hypothesis testing, A/B testing, regression analysis, Bayesian methods
- Causal inference: difference-in-differences, CUPED, propensity scores
- Time series: forecasting with Prophet, ARIMA or gradient boosting
- Deep learning and NLP: PyTorch or TensorFlow, Hugging Face, LLM evaluation
- Data tools: Snowflake, BigQuery, Spark or PySpark, dbt, Airflow
- MLOps and cloud: MLflow, Docker, AWS SageMaker, GCP Vertex AI or Azure ML
- Visualization: Tableau, Looker, Power BI, matplotlib
Soft skills matter, but prove them in bullets instead of listing them. "Strong communicator" means little; "Presented forecast results to the supply chain team in a dashboard now used in weekly ordering meetings" shows communication and impact together.
Certifications are optional for data scientists. A cloud certification from AWS, Google Cloud or Microsoft Azure can help if the job post asks for that cloud, but projects and measurable results carry more weight than course certificates.
ATS Keywords for Data Scientist Resumes
An ATS ranks resumes by how closely they match the job description, so copy the exact terms from the post you are applying to (if they are true for you). These appear in most data scientist job descriptions:
| Keyword group | Keywords to include (if you have the experience) |
|---|---|
| Core | data science, machine learning, statistical modeling, predictive modeling, data analysis |
| Languages and libraries | Python, SQL, R, pandas, scikit-learn, XGBoost, PyTorch, TensorFlow |
| Statistics and experiments | A/B testing, hypothesis testing, experimental design, causal inference, regression |
| Data platforms | Snowflake, BigQuery, Spark, Databricks, dbt, Airflow, ETL |
| Deployment | MLOps, MLflow, Docker, AWS, GCP, Azure, model monitoring |
| Business | stakeholder management, KPI, forecasting, churn, pricing, recommendation systems |
Use each keyword inside a bullet with a result where you can, rather than only in a skills list. Our ATS resume guide explains how these systems read and rank a resume.
Common Data Scientist Resume Mistakes
- Model metrics with no business result. "Achieved 0.92 accuracy" says nothing about value, and on imbalanced data it can hide a weak model.
- Listing every library you have imported. Ten tools you can discuss in depth beat thirty you cannot.
- Course projects that every applicant has (Titanic survival, Iris classification, MNIST digits). Replace them with a project built on data you chose.
- Skill bars and self-ratings such as "Python 4/5". They mean nothing to a recruiter and can break ATS parsing.
- Hiding the statistics. Many resumes mention only machine learning; many interviews also test experiments and probability.
- One resume for every job. A product analytics role, a forecasting role and an NLP role want different projects and keywords at the top.
Data Science Jobs in Numbers
Demand for data scientists is still growing much faster than the job market overall.
35% — projected growth in U.S. data scientist jobs from 2025 to 2035, much faster than average (U.S. Bureau of Labor Statistics)
According to the BLS Occupational Outlook Handbook, there were about 275,600 data scientist jobs in 2025, with about 24,800 openings projected each year. The BLS also notes that data scientists typically need at least a bachelor's degree in mathematics, statistics, computer science or a related field, and some employers prefer a master's or doctoral degree.
Frequently Asked Questions
What should a data scientist resume include?
A data scientist resume should include a short summary, work experience with measurable bullet points, a grouped technical skills section (languages, machine learning, statistics, data tools), education, and links to GitHub or a portfolio. Entry-level candidates should add 2–3 projects with a dataset, method, metric and baseline.
What is the best resume format for a data scientist?
A one-page, single-column, reverse-chronological format saved as a PDF works best. It is easy for recruiters to scan and parses cleanly in applicant tracking systems. Avoid skill bars, photos, tables for layout and two-column designs.
How long should a data scientist resume be?
One page for students and data scientists with under about eight years of experience. Senior data scientists, managers and PhDs with publications can use two pages, but the strongest results should still be on the first page.
What skills should I put on a data science resume?
Python and SQL, machine learning (regression, classification, gradient boosting), statistics and A/B testing, data tools such as Snowflake, Spark or dbt, and a visualization tool like Tableau. Add deep learning, NLP, causal inference or MLOps when the job asks for them and you have used them.
How do I write a data scientist resume with no experience?
Lead with Education and Technical Skills, then add 2–3 projects that use real or public data, compare against a baseline and report a clear result. Include any internship, research or analysis work from your current job, and show statistics as well as machine learning.
Should I put Kaggle competitions or GitHub projects on my resume?
Yes, if they show real work. Link a GitHub repository with a clear README, and list a Kaggle competition only with your result (for example, a top-10% finish) and what you learned. A project on data you chose usually says more than a tutorial notebook.
Do I need a master's degree or PhD to get a data scientist job?
Not always. The BLS says data scientists typically need at least a bachelor's degree in mathematics, statistics, computer science or a related field, and some employers require or prefer a master's or doctoral degree. Strong projects and results from an analyst or engineering job can make up for a missing advanced degree.
How much do data scientists make?
In the United States, the median annual wage for data scientists was $120,230 in May 2025, according to the U.S. Bureau of Labor Statistics. The BLS projects data scientist employment to grow 35% from 2025 to 2035.
Build Your Data Scientist Resume for Free
The button below opens the builder with the same Jake template used in the examples above. Add your projects and experience, check them with the built-in ATS score, and download a clean PDF. No sign-up is needed to start, and the free plan includes 8 PDF downloads a month.
Turn your models, experiments and projects into a data scientist resume that gets interviews.
Build My Data Science Resume FreeApplying for related roles too? See our machine learning engineer resume example, data engineer resume example and business analyst resume example, or browse all resume templates.